01
Deploy agents and models
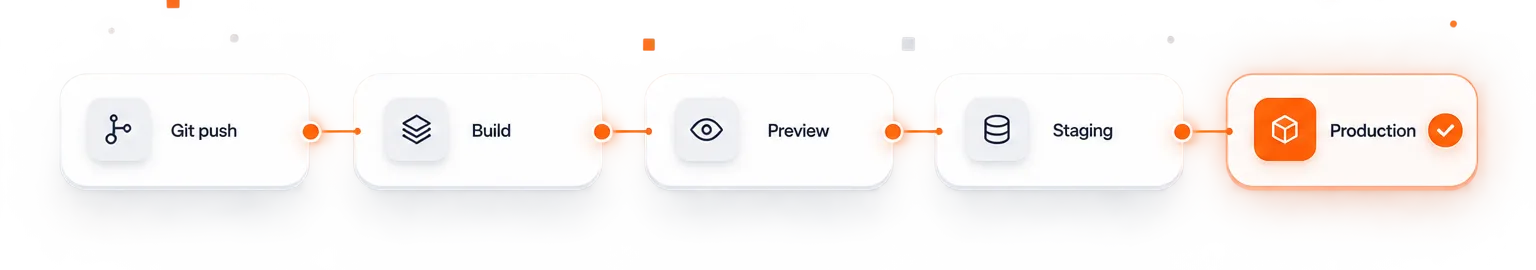
Promote from Git, a container, or the Metrune SDK. Keep secrets, model configuration, and scaling rules consistent across preview, staging, and production.
Versioned releases · isolated environments · instant rollback
Deploy agents and model-powered services, trace every run, control token spend, and roll back regressions from one production control plane.
Last 24 hours
Success rate
98.7%
P95 latency
1.84s
Tokens
8.4M
Model cost
$1,286
Agent runs
42,891 total
Recent runs
View traces
support-router
claude-4-sonnet
claude-4-sonnet
Completed
invoice-review
gpt-5
gpt-5
Completed
research-agent
gemini-2.5-pro
gemini-2.5-pro
Running
ticket-triage
gpt-5-mini
gpt-5-mini
Completed
Works with the stack you already run
One operating layer
Metrune connects the release, runtime, and business signals engineering teams need to operate AI without stitching together five separate tools.
01
Promote from Git, a container, or the Metrune SDK. Keep secrets, model configuration, and scaling rules consistent across preview, staging, and production.
Versioned releases · isolated environments · instant rollback
02
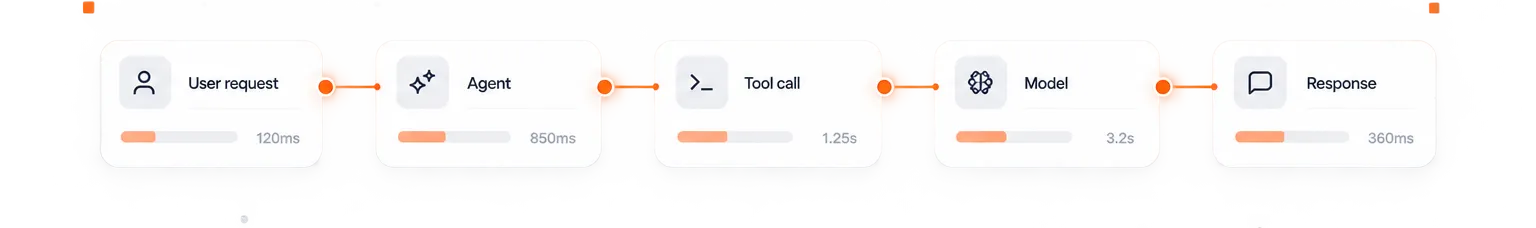
See prompts, responses, tool calls, retrieval steps, logs, and errors as one trace. Follow a request across agents, models, APIs, and infrastructure.
OpenTelemetry native · searchable logs · trace timelines
03
Attribute tokens and provider spend to an agent, release, environment, customer, or team. Set budgets before usage becomes an incident.
Cost attribution · budget alerts · model comparisons
Total tokens
8,418,271
Model cost
$1,288.72
Spend by model
04
Track latency, success rate, tool failures, and model regressions against production SLOs. Alert the right team and recover with the deployment history already attached.
SLO monitoring · alert routing · deployment correlation
Success rate
98.7%
Meeting objective
P95 latency
1.84s
Meeting objective
Error rate
0.21%
Meeting objective
Built for production
Move from an alert to the exact trace, model call, release, and owner without losing context.
Trace steps
2.84s
Selected span
claude-4-sonnet
Input
4,218 tokens
Output
982 tokens
Cost
$0.0412
output.summary
The account is eligible for an automatic adjustment. I verified the invoice, matched the subscription event, and prepared the corrective action for review.
Release intelligence
Metrune connects deployments to latency, failures, token usage, and cost. When a regression lands, the responsible release and owner are already in view.
4m 12s
Mean recovery time
100%
Changes attributed
Incident timeline
INC-284 · latency regression
14:32
Release v2.18.0 deployed
Production · 3 services · Maya Chen
14:39
Latency threshold crossed
support-router · p95 2.31s
14:41
Regression correlated
Retrieval step added 480ms
14:44
Release rolled back
v2.17.3 restored · SLO recovered
Deploy with confidence
Deploy versioned agent services to your own Kubernetes clusters or ours, and connect runtime health with model-level traces and release history.
99.95%
Uptime (SLA)
Global
Multi-region
Auto-scale
On demand